Spatial Audio & Immersive Music for Enka: Kayōkyoku, Ryūkōka & Mood Kayō
Spatial9 Team · · Updated · 19 min read
Part of the series Spatial audio and immersive music by genre.
Key takeaways
- Spatial audio for enka places the voice close at front centre with a soft centred bass, the tremolo guitar and shakuhachi on the front sides, the strings in a moderate arc and a warm hall behind.
- The cocktail party effect means a voice is easier to follow when it comes from a different direction from the band, so keeping the singer centred and the strings to the sides protects the words and the kobushi.
- Enka is a still, front stage music, so avoid panning moves and let a generous hall with a short pre-delay carry the emotion of the long notes.
- The enka immersion profile scores width 3, height 2, movement 1, low-end focus 2 and space 4 out of 5.
Enka is a style of Japanese popular song known for slow, sorrowful melodies and a richly ornamented voice. The word first appeared in the Meiji era, in the 1880s, as a short form of enzetsu no uta, "speech songs" sung in the street by supporters of the Freedom and People's Rights Movement to spread political ideas. Later street singers called enka-shi, such as Soeda Azembō, sold song sheets and sang about daily life. The modern sound grew from the ryūkōka of the 1920s and 1930s, when record companies and radio created Japan's first popular song industry. The composer Koga Masao wrote melodies so recognisable that they became known as "Koga melody", including "Sake wa Namida ka Tameiki ka", sung by Fujiyama Ichirō in 1931. After the war, kayōkyoku became the broad name for Japanese popular song, and in the 1960s enka took shape as its own genre, with singers such as Misora Hibari, Kitajima Saburō, Mori Shin'ichi and later Ishikawa Sayuri, Yashiro Aki and Itsuki Hiroshi. Enka melodies often use the yonanuki scale, a five-note scale that leaves out the fourth and seventh degrees, and singers use kobushi, a quick, controlled turn in the voice. The band usually blends strings, guitar, bass, drums and brass with Japanese instruments such as the shakuhachi and shamisen. Songs speak of longing, harbours, sake, snow, lost love and home, and they remain a fixture of NHK's year-end Kōhaku Uta Gassen. Enka suits spatial audio because the voice carries the whole story and the room gives it warmth. This guide covers how spatial audio for enka works, where to place each element and how to make an immersive enka mix. For the basics, see what spatial audio is.
Why enka works in spatial audio
Enka is built around one voice. The singer holds long notes, bends them with kobushi and lets them swell with vibrato. A tremolo guitar or a shakuhachi often plays the introduction and answers the voice between lines. Strings add a soft pad and rise at the chorus. Bass and drums keep a gentle, steady pulse in the background. In stereo the strings, guitar and voice can blend into one thick layer, and the small details of the singing get lost. In an immersive mix the voice sits close and clear in the centre, the instruments that answer it have their own places in front, and a warm hall gives every long note space to fade.
The rule: the voice close in the centre, the band calm around it. Keep the singer near and steady, set the answering instruments on the front sides and let a warm, natural hall carry the emotion.
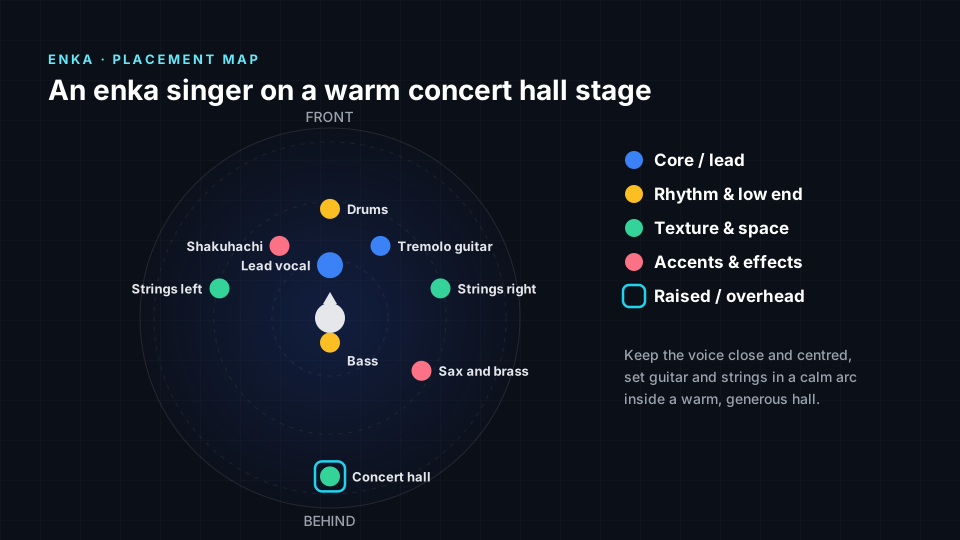
Immersive music for enka: what listeners hear
- A voice that feels close. The singer sits near and centred, so every kobushi turn and breath reaches the listener with no blur.
- Answers from the front sides. The tremolo guitar and shakuhachi reply to the voice from left and right, so each phrase becomes a quiet dialogue.
- Strings like a soft curtain. The string section opens to the sides and slightly back, adding warmth without covering the words.
- A calm, still stage. Nothing travels around the listener. The emotion comes from the voice and the room, not from movement.
Where to place each element in an enka mix
| Element | Position | Height | Why it works |
|---|---|---|---|
| Lead vocal | Front centre | Ear level | The voice carries the story and the emotion |
| Bass | Centre | Low | A soft, steady foundation under the song |
| Tremolo guitar | Front right | Ear level | The classic intro and answers to the voice |
| Shakuhachi | Front left | Ear level | A breathy Japanese colour between lines |
| Strings left | Left | Ear level | One side of the warm string pad |
| Strings right | Right | Ear level | The other side of the string pad |
| Drums | Front centre, further back | Ear level | A gentle pulse that stays behind the voice |
| Sax and brass | Behind right | Ear level | Fills and nightclub colour in mood kayō |
| Concert hall | Behind | Raised | A warm room that lets long notes fade |
The psychoacoustics behind enka placement
Every position in the table above follows how the ear and brain locate sound. Here is the reason behind the main choices for enka.
- The voice stays clear among the band. Listeners can follow one voice among many sounds more easily when the voice comes from a different direction from the rest. This is the cocktail party effect (Bronkhorst). Keeping the singer centred and close, with the strings to the sides, protects the words and the kobushi.
- Guitar, shakuhachi and voice in different places. The brain groups sounds into streams by pitch, timing and direction. This is auditory stream segregation (Bregman). Giving the answering instruments their own front positions lets the ear hear a call and a reply instead of one blended line.
- Bass stays centred. The ear finds almost no direction in frequencies below roughly 80 to 100 Hz, so the bass gains nothing from being spread. A centred, soft bass keeps the song grounded without drawing attention (Blauert).
- A hall with side reflections. Early reflections arriving from the sides make a sound feel wider and more enveloping. This is spatial impression from early lateral reflections (Barron and Marshall). Clear side reflections give enka the feel of a concert hall while the direct voice stays close.
The immersion profile for enka
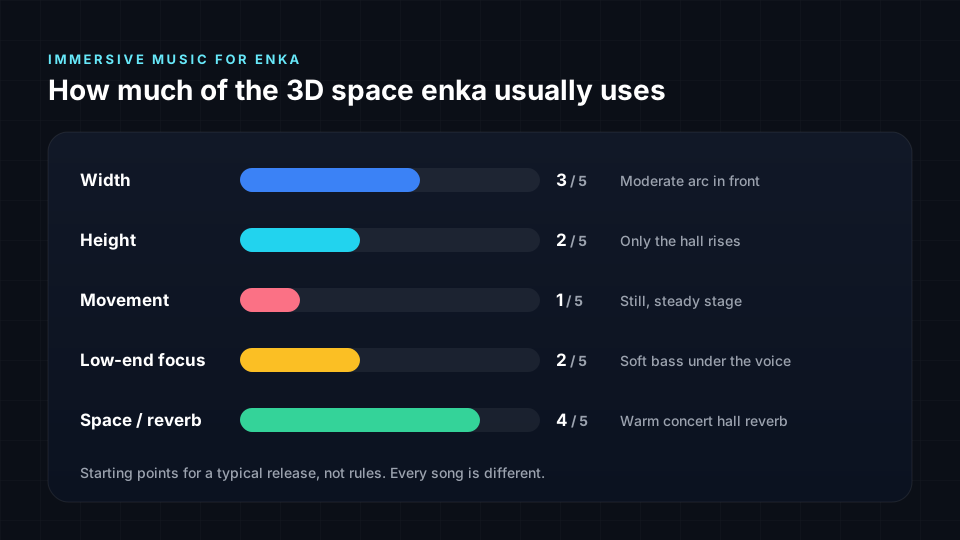
Width scores 3 because the band forms a moderate arc in front of the listener, with strings and answering instruments to the sides but nothing far around. Height is 2, since only the hall reflections rise above ear level and the singer and band stay on one plane. Movement is 1: enka is still and steady, and the drama comes from the voice, so every element stays in place. Low-end focus is 2, because the bass and drums play softly underneath and the music does not rely on heavy low end. Space is 4, since enka is sung in concert halls and on large television stages, and a warm, generous reverb is part of its classic recorded sound.
Tips for an immersive enka mix
- Keep the voice close. Place the singer at front centre with little reverb on the direct sound, so kobushi, vibrato and breath stay clear.
- Give the answers a place. Set the tremolo guitar and shakuhachi on opposite front sides so their replies to the voice are easy to follow.
- Open the strings gently. Spread the strings to the sides and a little back, and keep them below the voice so the words always come first.
- Keep everything still. Avoid panning moves or rotating effects. A calm, fixed stage suits the long, sad lines of enka.
- Use a warm hall. A generous reverb suits the style, but add a short pre-delay so the voice stays in front of the room.
Enka styles: Kayōkyoku, Ryūkōka and Mood Kayō
The core placement holds for every style here: the voice close at the centre, the band in a calm arc and a warm room around the listener. What changes is the size of the orchestra, the mix of Western and Japanese instruments and how much nightclub or dance colour the style carries.
Kayōkyoku
Kayōkyoku is the broad name for Japanese popular song of the Shōwa era. NHK radio began using the term in the late 1920s as another name for ryūkōka, and after the war it came to cover almost all mainstream Japanese song, from enka to the idol songs of the 1970s and 1980s. Many enka singers also sang kayōkyoku, and the two share composers, lyricists and orchestras. Kayōkyoku arrangements often use a full studio band with strings, brass, electric guitar and backing singers. Keep the lead vocal close and centred, the strings to both sides, brass behind right and backing voices in a soft arc behind the singer. A warm studio or concert hall sound suits the style.
Ryūkōka
Ryūkōka means "popular song" and names the Japanese popular music of the early recording era, from the 1910s to the 1950s. "Kachūsha no Uta", sung by the actress Matsui Sumako in 1914, is often called the first ryūkōka hit. In 1929 "Tokyo Kōshinkyoku", sung by Satō Chiyako, showed how records and films could launch a song nationwide, and in the 1930s Koga Masao and Hattori Ryōichi wrote many of the best-known melodies. After the war, "Ringo no Uta" by Namiki Michiko became a symbol of hope. Most ryūkōka recordings are in mono, with a small orchestra, guitar or accordion and a single voice. Keep the voice centred and close, place the small orchestra in a narrow arc in front and add a modest room. Do not spread old recordings too wide, or the voice can lose its body.
Mood Kayō
Mood kayō grew up in the 1950s and 1960s, during Japan's period of rapid growth, as the music of city nightlife. It blended kayōkyoku songwriting with jazz, Latin and Hawaiian sounds. Frank Nagai, known for his deep voice, sang "Yūrakuchō de Aimashō" in 1957, and male vocal groups such as Wada Hiroshi and Mahina Stars made the sound of smooth harmony and steel guitar popular. Songs often describe bars, rain and city streets at night. Keep the lead vocal centred and close, set the group harmonies in a soft arc behind, put the saxophone behind right, the steel or electric guitar front right and Latin percussion such as bongos or maracas to the sides. A warm, slightly dark lounge room suits the style better than a large hall.
Related styles such as the trot of Korea and the slow nightclub ballads of Taiwan and Hong Kong follow the same idea: keep the voice close in the centre, the band in a calm arc and a warm room around the listener.
Dolby Atmos and object-based mixing for enka
Dolby Atmos mixes enka as a channel bed plus objects placed anywhere in the room. Most listeners will hear the mix on headphones through binaural rendering on Apple Music, Tidal or Amazon Music. The channel bed holds the low end and room reverb, while objects allow precise placement of the singer and acoustic instruments. Spatial9 helps plan these placements for every format, ensuring the emotional core of the song translates perfectly.

How the Atmos plan differs from the placement map. This Dolby Atmos plan changes several placements from the Ambisonics map. The map put the bass behind and right, but Atmos practice keeps the bass in the front bed with the LFE channel. The sax and brass were to the side and right; this plan moves them to the front right stage to keep the band together. The concert hall was behind, right and raised, but here it becomes a full bed to surround the listener.
Beds and objects for each enka element
| Element | Atmos role | Where it plays in 7.1.4 | Binaural mode | Why |
|---|---|---|---|---|
| Lead vocal | Object | Ear level, front of the room, centre (X 0, Y 0.6, Z 0) | Near | The voice carries the story and needs a clear, intimate focus. |
| Bass | Bed | Centre plus LFE (C + LFE) | Off | Keeps the low foundation solid and centred without distracting from the vocal. |
| Tremolo guitar | Object, small size | Ear level, front of the room, right (X 0.5, Y 0.7, Z 0) | Mid | Answers the vocal from the front right stage with clear separation. |
| Shakuhachi | Object, small size | Ear level, front of the room, left (X -0.5, Y 0.7, Z 0) | Mid | Balances the guitar on the left to answer the singer between lines. |
| Strings left | Object, medium size | Ear level, front of the room, far left (X -0.8, Y 0.3, Z 0.2) | Mid | Forms a soft, wide curtain on the left side of the singer. |
| Strings right | Object, medium size | Ear level, front of the room, far right (X 0.8, Y 0.3, Z 0.2) | Mid | Completes the string pad on the right side for a warm blend. |
| Drums | Object, small size | Ear level, front wall, centre (X 0, Y 0.9, Z 0) | Mid | Sits behind the singer to provide a gentle, steady pulse. |
| Sax and brass | Object, small size, moving | Ear level, front of the room, right (X 0.7, Y 0.5, Z 0). Moving: Steps slightly wider during instrumental fills to add nightclub colour, ending at ear level, middle of the room, far right | Mid | Adds mood kayo colour from the side without masking the main vocal. |
| Concert hall | Bed | Whole 7.1.2 bed | Far | Wraps the band in a warm room that lets long notes fade. |
Dolby Atmos settings for enka
- LFE. Route the bass and kick to the bed and send them to the LFE channel to ensure a solid foundation. Objects do not have an LFE send.
- Object size. Keep the lead vocal and solo instruments on point or small sizes for sharp focus. Use medium sizes for the strings to create a softer, wider curtain.
- Height. Keep the singer and band at ear level. Use height only for the concert hall reverb to create a natural, enveloping acoustic space.
- Binaural render. Set the vocal to near for intimacy, the band to mid, and the reverb to far. Never leave everything on off, as labels will reject the master.
- Stage depth. Pull the vocal off the front wall to create distance between the singer and the drums, giving the enka arrangement natural acoustic depth.
Enka across immersive formats
| Format | How it carries sound | What it means for enka |
|---|---|---|
| Dolby Atmos | Hybrid: a 7.1.2 channel bed plus up to 118 objects placed with X, Y and Z metadata | Dolby Atmos uses a channel bed and objects to place the enka singer clearly in front of the band. |
| Sony 360 Reality Audio | Object-based, built on MPEG-H 3D Audio: every sound is an object on a sphere | Sony 360 Reality Audio places every enka instrument as an object on a sphere with no channel bed. |
| MPEG-H 3D Audio | Channels, objects and Higher Order Ambisonics in one stream, with optional listener control | MPEG-H 3D Audio carries channels and objects, allowing broadcasters to let listeners adjust the enka vocal level. |
| Auro-3D | Channel-based: a height layer above 5.1 or 7.1, with an optional overhead channel | Auro-3D uses fixed height channels rather than objects to add the concert hall acoustic above the enka band. |
| Eclipsa Audio (IAMF) | Channel-based and scene-based (Ambisonics) audio elements; no objects | Eclipsa Audio uses IAMF to carry channels and Ambisonics, so an Atmos enka mix must be rendered to channels. |
| Ambisonics | Scene-based: the whole sound field, decoded to any speaker layout or to headphones | Ambisonics stores the enka mix as a complete spherical sound field that decodes to any speaker layout. |
| ADM BWF | Open exchange file (ITU-R BS.2076 metadata in a BW64 file) for channels, objects and scenes | ADM BWF is the standard file format delivered to streaming services for an immersive enka master. |
Delivery checklist for a enka Dolby Atmos release
- Master file. ADM BWF at 48 kHz and 24-bit, with no more than 128 channels: a 10-channel 7.1.2 bed plus up to 118 objects.
- Loudness. Integrated loudness no higher than -18 LKFS and true peak no higher than -1 dBTP, measured to ITU-R BS.1770.
- Binaural metadata. Set Off, Near, Mid or Far for every bed and object. Masters with everything left on Off are rejected.
- Re-renders. Listen to the 5.1, stereo and binaural re-renders before delivery, because most people will hear one of them.
Check the Apple Music spatial render on headphones to ensure the kobushi vocal details remain clear and intimate.
How to make immersive enka from stereo
Spatial9 can create spatial audio from a stereo track in a few steps:
- Upload your stereo master or your stems.
- Spatial9's AI separates and places each part, pulling the voice, tremolo guitar, shakuhachi, strings and brass apart even from older orchestral recordings, and setting the band in a calm arc around a close, centred voice.
- Preview it in binaural on headphones.
- Export Eclipsa Audio, ADM, binaural or Ambisonics.
- Publish a video. Create a YouTube-ready video with your immersive audio and publish it directly.
For related guides, read spatial audio for Japanese traditional music and spatial audio for Cantopop. Every guide is listed in spatial audio and immersive music by genre.
Frequently asked questions
Does this guide cover Kayōkyoku, Ryūkōka and Mood Kayō?
Yes. Kayōkyoku sets a close voice in front of a full studio band with strings and brass. Ryūkōka keeps older, often mono recordings narrow, with a small orchestra and a modest room. Mood kayō adds group harmonies, saxophone, steel guitar and Latin percussion inside a warm lounge.
Can I make an enka mix in Dolby Atmos or Eclipsa Audio?
Can I make an enka mix in Dolby Atmos? Yes, Dolby Atmos is the standard format for immersive music on streaming services. You can mix the band into the channel bed and use objects for the singer, shakuhachi and guitar. Remember that Dolby Atmos and Eclipsa Audio require separate deliveries, as Eclipsa uses IAMF and does not support objects. Always check the Apple Music headphone render separately, because it applies its own spatial processing that can change how the vocal sits in the mix.
Should enka elements be beds or objects in Dolby Atmos?
Should enka elements be beds or objects in Dolby Atmos? The bass and the concert hall reverb should be routed to the bed. The bed handles the low-frequency foundation and the wide, enveloping acoustic space. The lead vocal, tremolo guitar, shakuhachi, strings, drums and brass should be objects. Objects allow you to pull the singer and acoustic instruments off the front wall for depth, keeping the voice perfectly focused and separate from the answering instruments.
Does a enka Dolby Atmos mix also work for Sony 360 Reality Audio and MPEG-H?
Does an enka Dolby Atmos mix also work for Sony 360 Reality Audio and MPEG-H? No, they are different formats and require their own mixing tools. Dolby Atmos uses a hybrid of a channel bed and objects. Sony 360 Reality Audio is built on MPEG-H 3D Audio and relies entirely on objects placed on a sphere, with no channel bed at all. You must create a separate master for Sony 360 Reality Audio to ensure the enka vocal and instruments are placed correctly.
Is spatial audio good for enka?
Yes. Enka centres on one expressive voice with a band that answers it and a warm room around it. Spatial audio keeps the voice close and clear, gives each answering instrument its own place and lets the long notes fade into a real sense of space.
Where should the voice go in an immersive enka mix?
Put the voice at front centre, close to the listener, with only a little reverb on the direct sound. The kobushi and vibrato carry the feeling of the song, so they need to stay clear and near.
Should the strings be wide or narrow?
Moderately wide. Spread them to the left and right and a little back, but not all the way around the listener. Enka is a front stage music, and strings that wrap too far can pull attention away from the voice.
How is enka different from fado in spatial audio?
Both are built on one expressive voice and a feeling of longing. Enka uses a fuller band with strings, guitar, drums and Japanese instruments in a concert hall, so it suits a moderate arc around the voice. Fado is usually a voice with Portuguese guitar and classical guitar in a small room, so it suits a narrower, more intimate layout.
Can I convert an old enka or ryūkōka recording to spatial audio?
Yes. Spatial9 uses AI to separate the voice, strings and other instruments from a stereo or mono recording. Separation is never perfect with older orchestral recordings, so keep the layout narrow and the room moderate.
Dolby and Dolby Atmos are trademarks of Dolby Laboratories. 360 Reality Audio, Auro-3D and other format names are trademarks of their respective owners. Spatial9 is not affiliated with or endorsed by Dolby Laboratories or these companies.
Sources
- Blauert, J. (1997). Spatial Hearing: The Psychophysics of Human Sound Localization, revised edition. MIT Press. Low-frequency, elevation, distance and motion cues.
- Mills, A. W. (1958). On the minimum audible angle. Journal of the Acoustical Society of America, 30(4), 237-246.
- Hebrank, J. and Wright, D. (1974). Spectral cues used in the localization of sound sources on the median plane. Journal of the Acoustical Society of America, 56(6), 1829-1834.
- Bronkhorst, A. W. (2000). The cocktail party phenomenon: a review of research on speech intelligibility in multiple-talker conditions. Acta Acustica united with Acustica, 86, 117-128.
- Barron, M. and Marshall, A. H. (1981). Spatial impression due to early lateral reflections in concert halls. Journal of Sound and Vibration, 77(2), 211-232.
- Neuhoff, J. G. (1998). Perceptual bias for rising tones. Nature, 395, 123-124.
- Bregman, A. S. (1990). Auditory Scene Analysis: The Perceptual Organization of Sound. MIT Press.
- Yano, C. R. (2002). Tears of Longing: Nostalgia and the Nation in Japanese Popular Song. Harvard University Asia Center.
- Dolby Laboratories. Dolby Atmos for content creators. Dolby Professional. professional.dolby.com. 7.1.2 bed, audio objects with X, Y, Z metadata and renderer re-renders.
- Production Expert. Mixing Dolby Atmos on headphones: a professional guide. production-expert.com. Binaural render modes Off, Near, Mid and Far.
- Universal Music Group. Content Guide: Dolby Atmos servicing asset specifications. contentguide.universalmusic.com. ADM BWF, 48 kHz, 24-bit, 128 channels, binaural metadata and -18 LKFS.
- International Telecommunication Union. Recommendation ITU-R BS.2076: Audio Definition Model.
- International Telecommunication Union. Recommendation ITU-R BS.2088: Long-form file format for the international exchange of audio programme materials with metadata (BW64).
- International Telecommunication Union. Recommendation ITU-R BS.2051: Advanced sound system for programme production.
- International Telecommunication Union. Recommendation ITU-R BS.1770: Algorithms to measure audio programme loudness and true-peak audio level.
- European Broadcasting Union. ADM related standards. adm.ebu.io.
- ISO/IEC 23008-3. Information technology. High efficiency coding and media delivery in heterogeneous environments. Part 3: 3D audio (MPEG-H 3D Audio).
- Herre, J., Hilpert, J., Kuntz, A. and Plogsties, J. (2015). MPEG-H 3D Audio: the new standard for coding of immersive spatial audio. IEEE Journal of Selected Topics in Signal Processing, 9(5), 770-779.
- Sony Corporation. 360 Reality Audio licensing. sony.co.jp. Object-based spatial audio based on MPEG-H 3D Audio.
- Alliance for Open Media. Immersive Audio Model and Formats (IAMF). aomediacodec.github.io/iamf. Channel-based and scene-based audio elements.
- Zotter, F. and Frank, M. (2019). Ambisonics: A Practical 3D Audio Theory for Recording, Studio Production, Sound Reinforcement, and Virtual Reality. Springer.
Take the stage
Upload a track to Spatial9 and hear the voice close at the centre with the band in a warm arc around you in minutes. Then export it or publish it straight to YouTube.